AI Automation
Cut receipt analysis from 4 minutes to 20 seconds
Customers forward a supermarket receipt and get a full basket breakdown back before they have put the shopping away — and when something goes wrong, they are told exactly what and why.

Stack
- n8n
- Supabase
- PostgreSQL
- OpenAI API
- Claude API
- Stripe
- MailerSend
~90%
faster analysis
4 min → 20–25 sec
~60%
fewer output tokens
zero downstream schema changes
Zero
silent failure paths
every terminal state emails someone
The product
Overview
PrediabetesBasket is a UK consumer app for adults with prediabetes. Users forward their online supermarket receipt to a personal email address; a few seconds later they receive a full basket analysis back — a traffic-light rating for every food item, a basket score, and personalised swap suggestions that get progressively more ambitious the longer they use the product.
The core promise is that the advice remembers you. If you bought the same sugary drink three weeks running, you do not get told "try a diet version" three times — you get moved up a ladder, one realistic step at a time, and the app recognises when you have improved.
That promise is what made this an interesting engineering problem rather than a thin API wrapper.
How it runs
Architecture
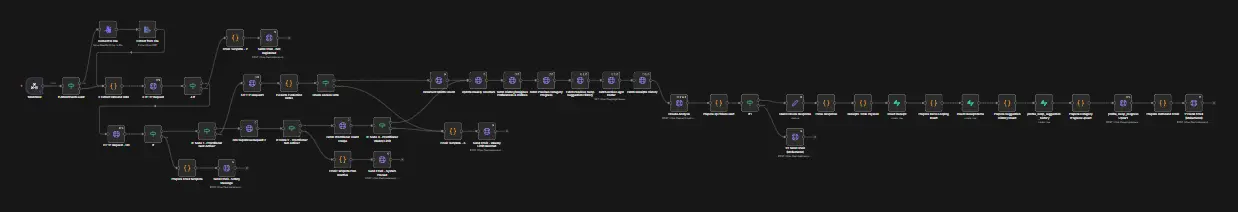
One inbound email triggers a gated, ordered pipeline — and every gate that can reject you tells you why.
Inbound email — forwarded receipt
n8n webhook — identify user by inbound email address
Eligibility & safety gate
blocked → explanatory email
Quota gate — plan / weekly / lifetime
blocked → upgrade email
Fetch context from Supabase
- dietary and religious preferences, dislikes
- previous category progress (swap ladder state)
- previous swap suggestion history (anti-repetition)
- recent receipt history (progress comparison)
- active legal footer (versioned, database-owned)
LLM analysis
API failure → categorised ops alert
Parse & validate JSON
Write across 4 Supabase tables — ordered, FK-dependent
Render & send HTML analysis email
Every branch terminates in a user-facing email. There is no silent failure path — if a receipt cannot be analysed, the user is told specifically why.
The performance work
Cutting analysis latency by ~90%
Large receipts of 30 items or more were taking four minutes end to end, with the LLM call alone accounting for over three of them. At that latency the product does not feel like a service, it feels broken — and per-receipt cost scaled with it.
The diagnosis
The instinct is to blame the input payload or the network. The data said otherwise: input was around 11.8k tokens — a single fast prefill pass — while output was hitting the 15k cap, and hitting it before finishing the receipt.
LLM latency is dominated almost entirely by autoregressive output generation, so wall-clock time was a near-linear function of tokens emitted, not tokens consumed. That reframed the problem entirely: the only lever that mattered was reducing what the model had to write.
Null-field discipline
items_json — A byte-for-byte duplicate of the items array. On a 50-item receipt this alone doubled the item payload.
health_reason — Identical to why_flagged, per item.
suggested_swap / not_ready_to_switch — Duplicates of alternative and small_step, per item.
legal_footer_text / legal_footer_json — Several hundred characters of legal boilerplate echoed back verbatim, despite the pipeline having just sent it to the model.
Green-item prose — Full explanatory text on green items, which the UI only ever renders as a summarised group.
None of these carried information the pipeline did not already hold. The fix was to instruct the model to emit them as literal null — explicitly telling it not to reason about them, not to populate them, just skip — and have n8n reconstruct the mirrored fields after parsing, from the source of truth.
Why a schema audit over a two-call split
The textbook fix for a slow generation step is to split it: a cheap classification pass, then detail generation for flagged items only. Why not do that?
I rejected the split for v1. The schema audit solved the same problem for free, and it shipped without touching a single downstream consumer.
Complexity you can avoid paying for is the best kind — and the measurement said the redundancy, not the architecture, was the cost.
The alternative
Two calls: classify cheaply, then generate detail only for flagged items. Genuinely lower output volume, and the standard answer.
What it cost
It doubles input cost, adds a network hop and a second failure point, and complicates debugging — to solve a problem a schema audit already solved.
| Before | After | |
|---|---|---|
| Large-receipt processing | ~4 min | ~20–25 sec |
| Output tokens, large receipt | 15,000 (truncated) | ~5–6,000 |
| Downstream schema changes | — | Zero |
Achieved with no change to the data any consumer receives — the app, the email, and all four database tables see exactly the same shape as before.
Data integrity
Defensive database writes
CHECK-constraint sanitisation — colour_rating must be green, amber or red; ladder levels must be 1–3. A single hallucinated value would otherwise fail the entire batch insert and take the receipt down. Shared helpers coerce out-of-range values to null rather than letting Postgres reject the batch.
NOT NULL pre-filtering — Rows missing required fields are dropped at the mapping stage instead of failing at insert time.
Orphan guards — If the parent receipt insert returns no ID, dependent writes short-circuit to an empty array rather than attempting invalid foreign keys.
Status short-circuits — Safety-blocked and errored receipts never contribute to swap history or ladder progress. From the user’s perspective those receipts did not happen, so the personalisation state must not move.
Normalisation consistency — Item names are lowercased, trimmed and internally whitespace-collapsed identically across every table, so "Fresh Milk" and "Fresh Milk" match on history lookup. Without this, anti-repetition silently degrades.
Failure modes
Production error handling
On an email-driven pipeline, a silent failure is indistinguishable from "nothing has happened yet" — so nothing is allowed to fail silently.
The Anthropic account was disabled mid-project after a credit exhaustion event during prompt-optimisation testing. The pipeline had no visibility into API failures — receipts simply vanished.
I built a failure handler that detects success positively, by checking for the expected response shape, rather than by enumerating error shapes. It then categorises the failure and sends a styled ops alert with a concrete recommended action: billing exhausted, invalid key, rate limited, permission denied, malformed request, content filtered, or upstream 5xx. Each alert carries the request ID, a retryability assessment and the affected profile, so triage is possible from the email alone without opening execution logs.
The same handler doubles as the workflow’s success gate, so there is one place that decides "did this work" rather than a scattered set of assumptions.
Provider migration
Delivery
Transactional email that survives real clients
Seven distinct templates: receipt analysis, safety-blocked, processing error, quota exhausted, eligibility notice, account confirmation, and internal ops alerts.
The interesting constraint was typography. The brand system is DM Serif Display and DM Sans — a superfamily pairing that reads beautifully on the web and is completely ignored by Outlook Desktop, which renders through Word, and by the Gmail mobile app, which strips @font-face and <link> outright. No amount of MSO conditional markup changes this; it is a hard limitation, not a bug to engineer around.
Rather than ship something that looked correct for the designer and broken for half the users, I moved to Georgia and Trebuchet MS — a universally installed pairing that preserves the serif/sans hierarchy the brand depends on, with Trebuchet reserved for uppercase eyebrows, badges and small-caps labels where a sans genuinely aids legibility at tight letterspacing.
Other production hardening
Table-based layout throughout — Stacked divs produce visible whitespace seams in several clients.
Table-drawn shapes — Dots and rules are drawn with tables rather than glyphs or emoji, which render inconsistently.
HTML escaping on every interpolated value — Product names come straight from receipt text — an unescaped ampersand in "Peas & Carrots" corrupts the markup.
Versioned legal footer — Assembled from a database record rather than hardcoded, so compliance wording can be updated without a deploy.
Outcome
Selected results
~90%
reduction in large-receipt processing time
4 min → 20–25 sec
~60%
reduction in output tokens per analysis
zero downstream schema changes
Zero
silent failure paths
every terminal state emails a user or an operator
1:1
provider migration
Anthropic → OpenAI, prompt logic unchanged
Retrospective
What I would take to the next build
Latency in LLM pipelines is an output-volume problem — Before reaching for architectural complexity — batching, splitting, streaming — audit what you are asking the model to write. The cheapest optimisation available here was deleting redundant fields from a schema, and it beat every structural alternative.
Give every failure a destination — The error-handling work felt like overhead until the API account was disabled, and it was the only reason anyone found out.
Trust the platform’s constraints — Two days could have gone into forcing brand fonts into Outlook. The correct answer was accepting the limitation and designing a fallback good enough that nobody notices.
Built as sole engineer on the backend, automation, data and integration layer, working alongside a product owner and a delivery manager. Client and infrastructure identifiers omitted.